NVIDIA/auto-ontology
- Source
- GitHub
- First trending
- Category
- RAG and search
- GitHub stars
- 5,013
- Main language
- Python
This page introduces an external open-source repository. It is not an HDATF product.
What it does
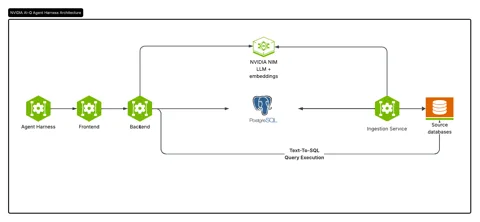
Auto Ontology builds a shared meaning layer over enterprise databases so agents can interpret business terms before querying data. Developers connect source databases and ingest their table and column metadata. Business terms, relationships, and SQL expressions form a semantic catalog stored in Postgres with vector search support. Users ask questions in natural language, and the application generates SQL and executes it against connected sources. Results can include an answer, the SQL, and returned rows. The MCP interface exposes glossary lookup, answerability checks, and question answering through a restricted tool set. Deployment combines a web gateway, Python services, Postgres, and configured model endpoints. Starting requires database access, authentication settings, and inference credentials or equivalent configured endpoints. Generated SQL and answers still require validation, and database credentials added through the UI remain unencrypted in Postgres unless Vault is fully configured.
License
Apache-2.0 Permissive, with a patent grant. Commercial use is allowed; keep the notices and state your changes.
More in this category
- patchy631/ai-engineering-hub
AI Engineering Hub collects tutorials and example code for developers learning LLMs, document retrieval and agents. It is a collection of projects grouped by difficulty and topic, not one finished service or a proprietary model. Examples cover document question answering, image text extraction, chat interfaces and MCP connections. The inspected Simple RAG example reads documents from a folder, builds a retrieval index and generates an answer from relevant passages. Its notebook connects LlamaIndex, llama3.2 through Ollama and HuggingFace embeddings, then streams an answer based on two retrieved passages. That example requires Python 3.10 or newer, Ollama, a notebook environment and separately supplied documents. Other projects use different models, external services and credentials, so their individual documentation and configuration must be checked. Downloading the repository does not activate every feature, and this review does not establish production readiness or retrieval quality. - StarTrail-org/LEANN
LEANN is a vector index and retrieval toolkit for users who want to search local documents and records without retaining a full stored embedding for every text chunk. It supports retrieval augmented generation, which means finding relevant source passages before asking a language model to answer. Inputs include documents such as PDF, text, and Markdown files, or records handled by the supplied source specific examples; outputs include matching passages and optional model generated answers. The document example reads files recursively with LlamaIndex and splits their contents into chunks before indexing. Its low storage approach uses a pruned graph and selectively recomputes embeddings, numerical representations of meaning, when the search needs them, with HNSW and DiskANN backend options. It requires a Python environment, an embedding model or endpoint, and a generation model for answers; native builds and optional scanned PDF extraction add platform and OCR dependencies. Models can run locally or through cloud APIs, so privacy depends on both the embedding and answer generation settings rather than the location of the index alone. Recomputing embeddings trades storage against computation and query latency, while extraction failures and model choice can affect what is actually found. The README's storage savings are author reported results under particular comparisons, not a guarantee for every collection or evidence of performance on our data. - metadist/synaplan-nextcloud
Synaplan Integration is a connector app that adds document summaries, translation and knowledge search chat to the Nextcloud file interface. It targets organizations already storing documents in Nextcloud and hosting providers operating those environments. It sends a selected file or question to a connected Synaplan server and displays a summary, translation or streamed answer. Uploading files into knowledge groups makes them available for RAG, which retrieves relevant documents to inform answers. Text extraction from binary documents such as PDF and Office files is handled by Synaplan's Tika functionality rather than by this app itself. Getting started requires a supported Nextcloud version from 33 through 35, PHP 8.2 or later, a running Synaplan instance and a valid API key. Operators can share one account, provision individual accounts or link existing Synaplan accounts, with individual mode keys stored encrypted on the server. Personal memories and image or video generation depend on the corresponding services and model configuration on the connected server. Changed files require a manual update through the dialog, while documentation and source distinguish automatic watched-folder processing as not yet implemented. - ARahim3/DigUp
DigUp is a menu bar app for Apple Silicon Macs on macOS 14 or later that searches the files in folders the user picks by their content. It is meant for people who want to find photos, screenshots, PDFs, documents, recordings and videos by describing them in their own words, and it is free and open source under the MIT license. The app runs EmbeddingGemma 2, Google DeepMind's multimodal embedding model (a model that turns text, images and sound into number vectors that can be compared), on the device. It reads images by what they show, screenshots also by their text through Apple's text recognition, PDFs page by page including scans, audio in overlapping 30-second windows, and video as a frame every few seconds plus its soundtrack. A result opens at the match where its app allows it, so a recording or video starts at its moment in QuickTime Player or IINA, and a PDF opens in Preview with words from the matching page placed in its search field. Inside, llama.cpp runs an 8-bit build of EmbeddingGemma 2 on the Mac's GPU, and the 768-dimensional vector made for every picture, page, passage and stretch of sound is stored in one SQLite file next to an FTS5 keyword index. A search compares the query vector with every stored vector and adds a boost for exact word matches, so invoice numbers and error codes in file names, document text and screenshots are found as written. It installs from the DMG on GitHub Releases or through Homebrew and needs no account, and on first launch it downloads 865 MB of model files from Hugging Face at a pinned revision and checks their size and SHA-256. According to the README, indexed content stays on the Mac, the network is used only for that download and a daily update check that can be turned off, and the app only reads files, skipping key files, certificates and hidden folders such as .ssh. After the folders are picked, the first indexing pass takes from a few minutes for a few hundred files to about an hour for a large Downloads folder, and a build from source also produces a digup command-line tool that can return search results to another program as JSON lines. The published releases, 0.6.0 and 0.6.1 from October 2026, are macOS DMGs only, and Windows and Linux builds exist in the code without a public release. The project's evals cover only English, Bengali and Arabic, and exact word matching cannot split languages written without spaces, such as Chinese, Japanese and Thai, into words. - xerj-org/xerj
XERJ is a search engine written in Rust that indexes local folders for AI coding agents and other programs, ships as one static binary, and implements the Elasticsearch REST API so existing Elasticsearch clients and Kibana can connect to it. The README's main use case is reference coding, in which an agent clones open-source projects close to its task, indexes them, and retrieves how they solved a problem as passages with file and line references instead of whole files found with grep. The xerj autoindex command turns the files in a folder into typed indices without a schema, parses source code with tree-sitter so symbols and line numbers are kept, and also handles files such as PDF, XLSX and mail. Search covers BM25 full-text, vector kNN and hybrid queries, and the /_memory API stores an agent's memories in a separate index per namespace and recalls them by keyword, meaning or vector. The xerj mcp command is a stdio MCP server with 13 tools that forwards calls to a node started separately, and xerj init registers XERJ with Claude Code and Cursor. It installs through an install script or binaries for Linux, macOS and Windows, the default embedder is offline feature hashing, and turning on the neural embedder downloads about 90 MB of model files once. The --insecure flag in the quick start turns off TLS and API key authentication so anyone who can reach the port is a superuser, while other starts turn on authentication with an admin key. SECURITY_MODEL.md lists limits such as TLS off by default, no field or document level security and no encryption at rest, and share links that open whole indices to guests. According to RERANK.md, a default node opens no outbound connections and sends no telemetry, and the features that send document text off the node, namely reranking through TypeSafe AI's Jev, proxy embeddings, the WAL tap and the S3 backend, work only after an operator turns them on. In the project's own study cited in the README (8 tasks in 4 languages), the agent using XERJ spent 9,982 output tokens against 26,477 for a grep-driven agent, and both had a solve rate of 16 of 16. The README says the gain holds for private or post-cutoff code and is neutral to harmful on popular libraries the model already knows, and the 40 times token saving in the repository description could not be traced to a file in the repository. The latest release at research time was the release candidate v1.0.0-rc.95 from 2026-10-12, the LICENSE file and GitHub metadata are both Apache-2.0, and code contributions require signing a CLA.
Only repositories in the ranked Trendshift lists are included, and the lists are used only to find candidates. We do not copy their ranks. Descriptions, licenses and star counts come from each GitHub repository. The notes are our own reading. We have not tested these projects, and a place on a trending list does not prove quality.